JetBrains AI
Supercharge your tools with AI-powered features inside many JetBrains products
Mellum2.1 Gets to Work: A Fast Open Model for Coding Agents
Trained with reinforcement learning in real environments, Mellum2.1 is built for coding agents and fast sub-agents that run on your own hardware.
Today, we’re releasing Mellum2.1, the next version of the 12B mixture-of-experts model we open-sourced in June. The architecture hasn’t changed since version 2: it’s still a compact, fast model with 2.5B active parameters, released under the Apache 2.0 license. What has changed is everything that happens after pre-training.
Mellum2 was fast, but it couldn’t work inside a repository at the level we wanted. After a summer of reinforcement learning in real environments, with millions of sandboxed runs across thousands of environments, Mellum2.1 can: it explores a codebase, edits files, and checks its own changes.
The changes we made in Mellum2.1
Almost all of the work for this version went into post-training, primarily reinforcement learning (RL).
- Reinforcement learning at a new scale: RL went from a short final stage to the main part of training. We ran many experiments on how to train both the methods and the data, and we kept what held up.
- More data, filtered harder: We added new RL tasks in math, competitive programming, science, tool use, and software engineering, combining open RL datasets with tasks we built ourselves. Open data often comes with broken tests, unverifiable answers, or tasks that are too easy or impossible for the model, so every source was filtered before it reached training.
- Real environments for agentic skills: We built the infrastructure to run thousands of RL environments in-house and launched millions of sandboxes over the course of training.
How Mellum2.1 performs
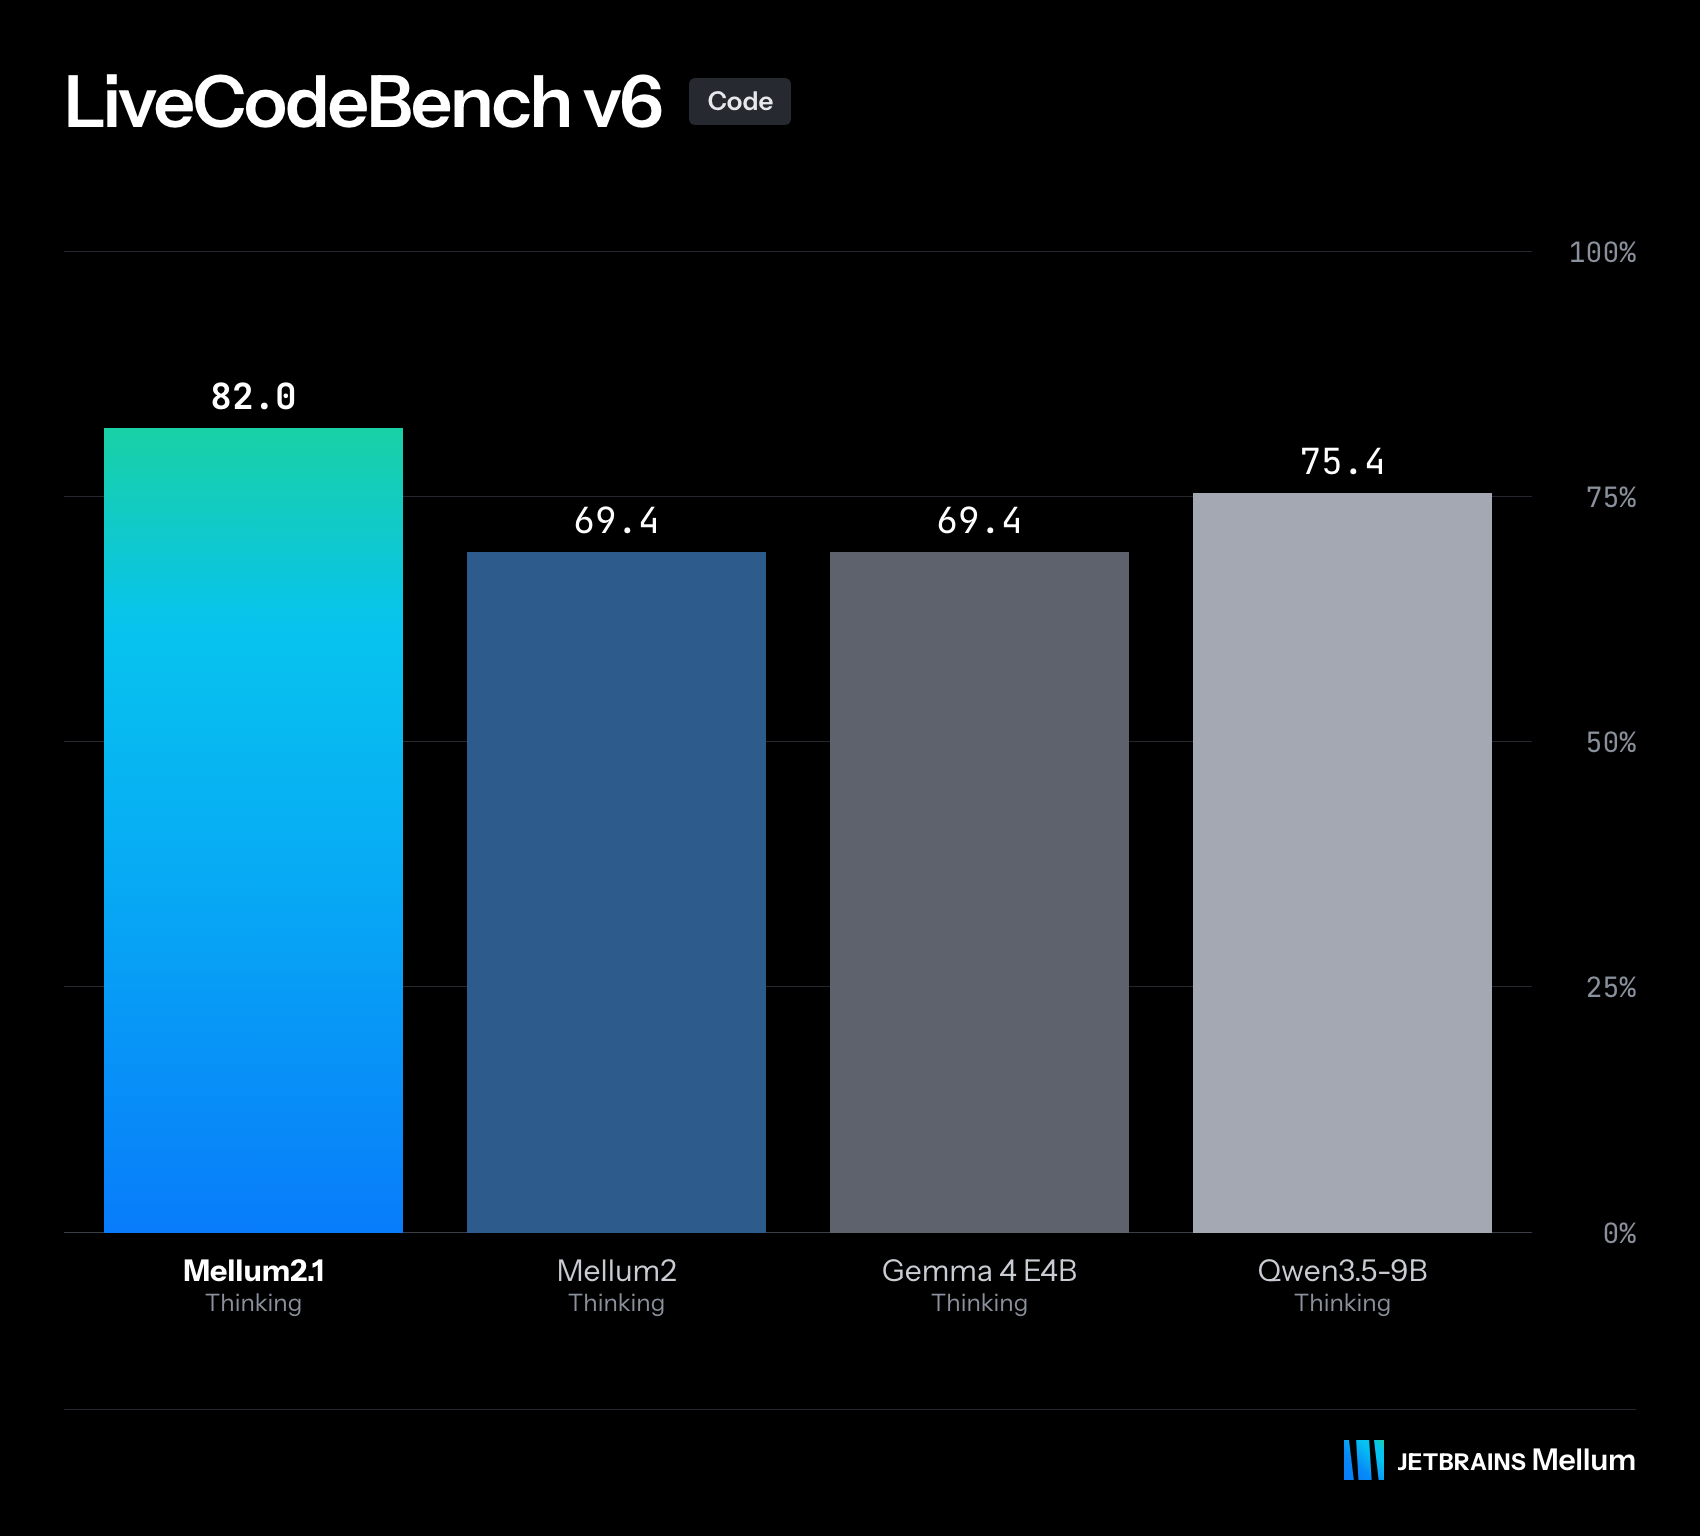
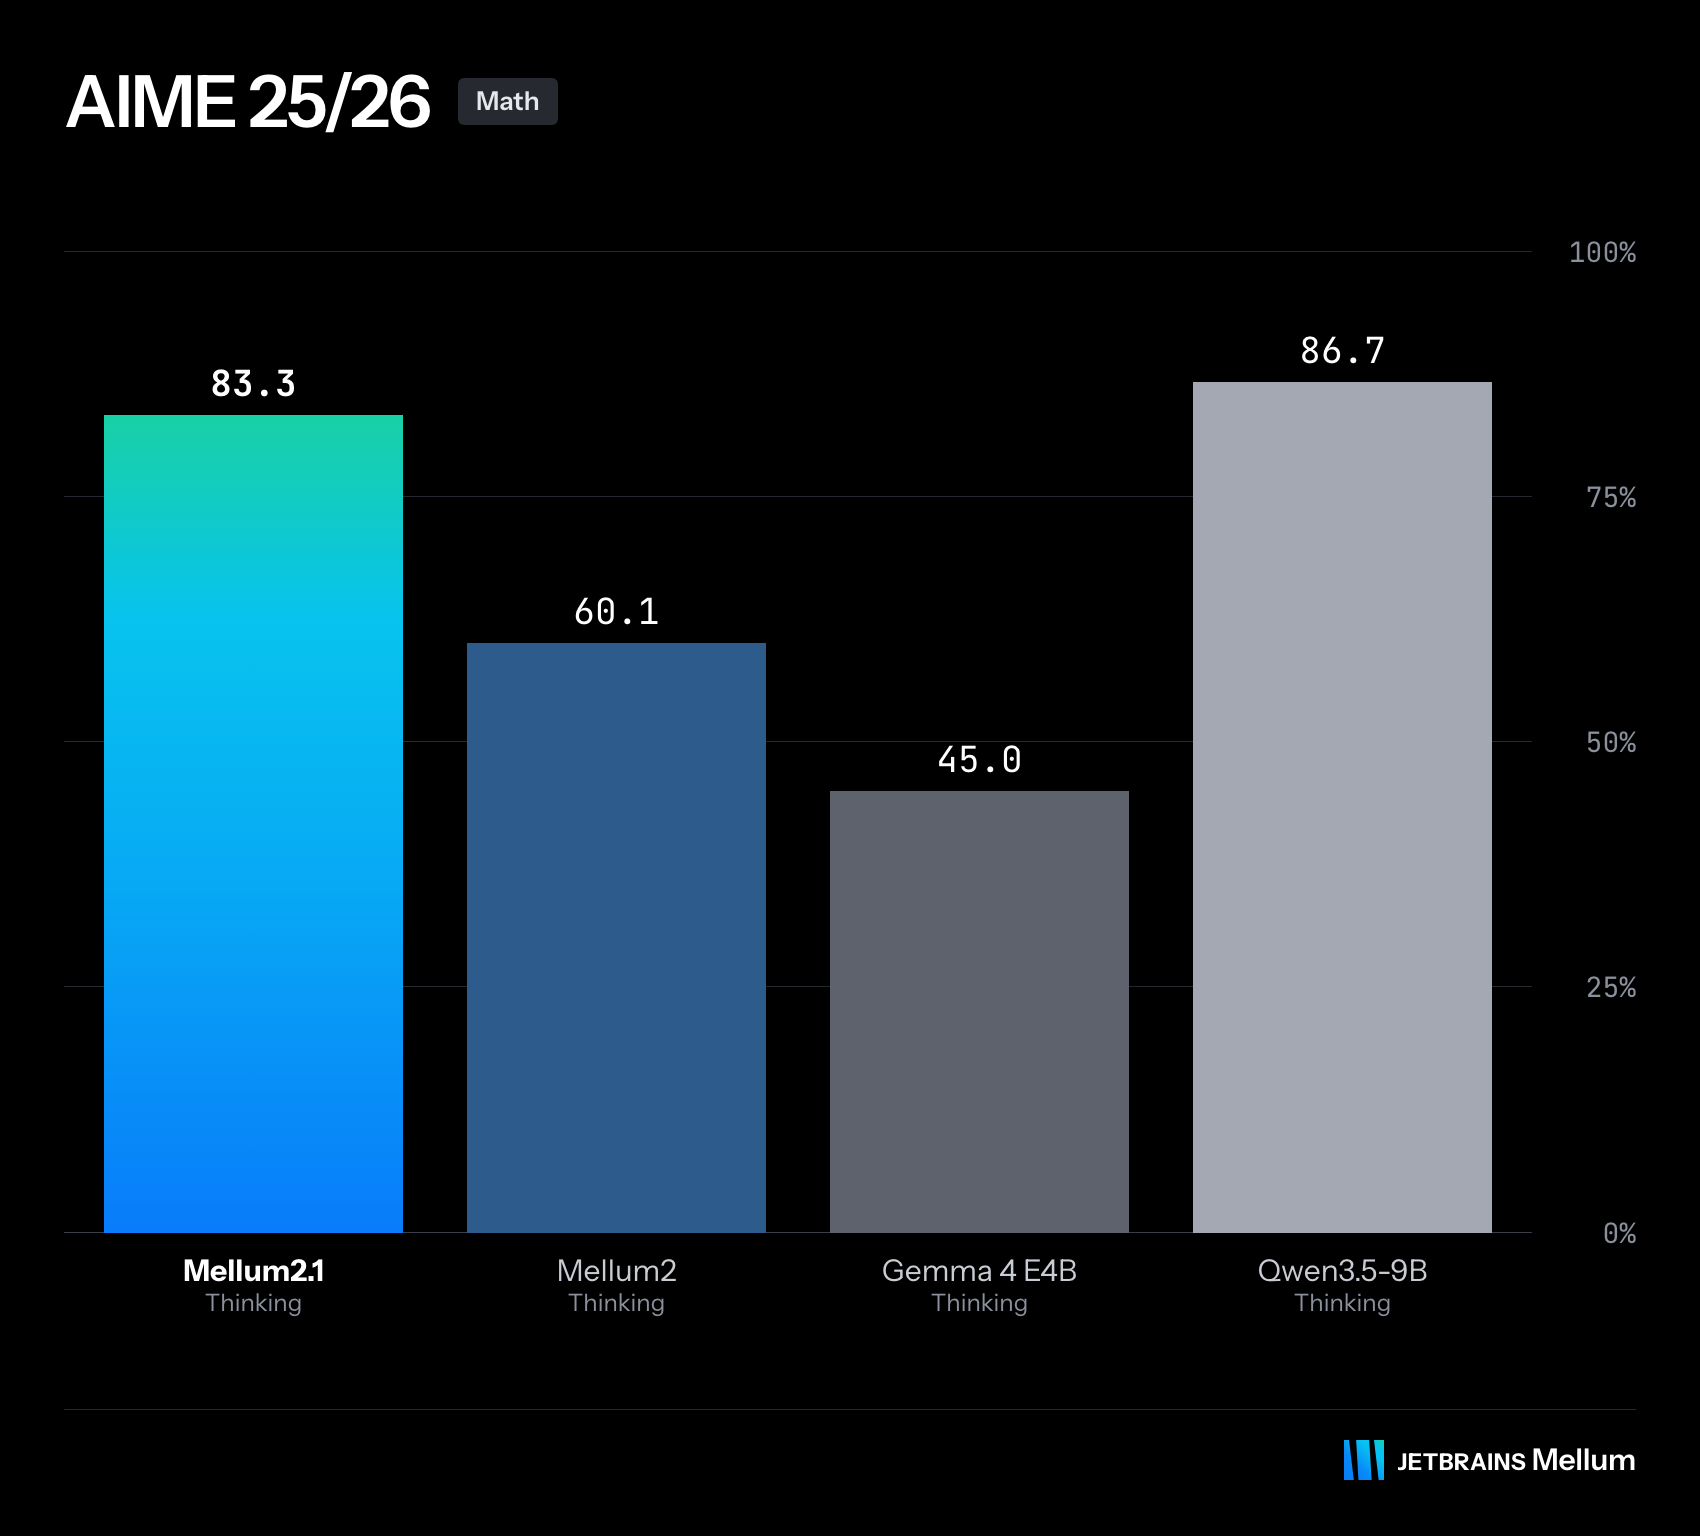
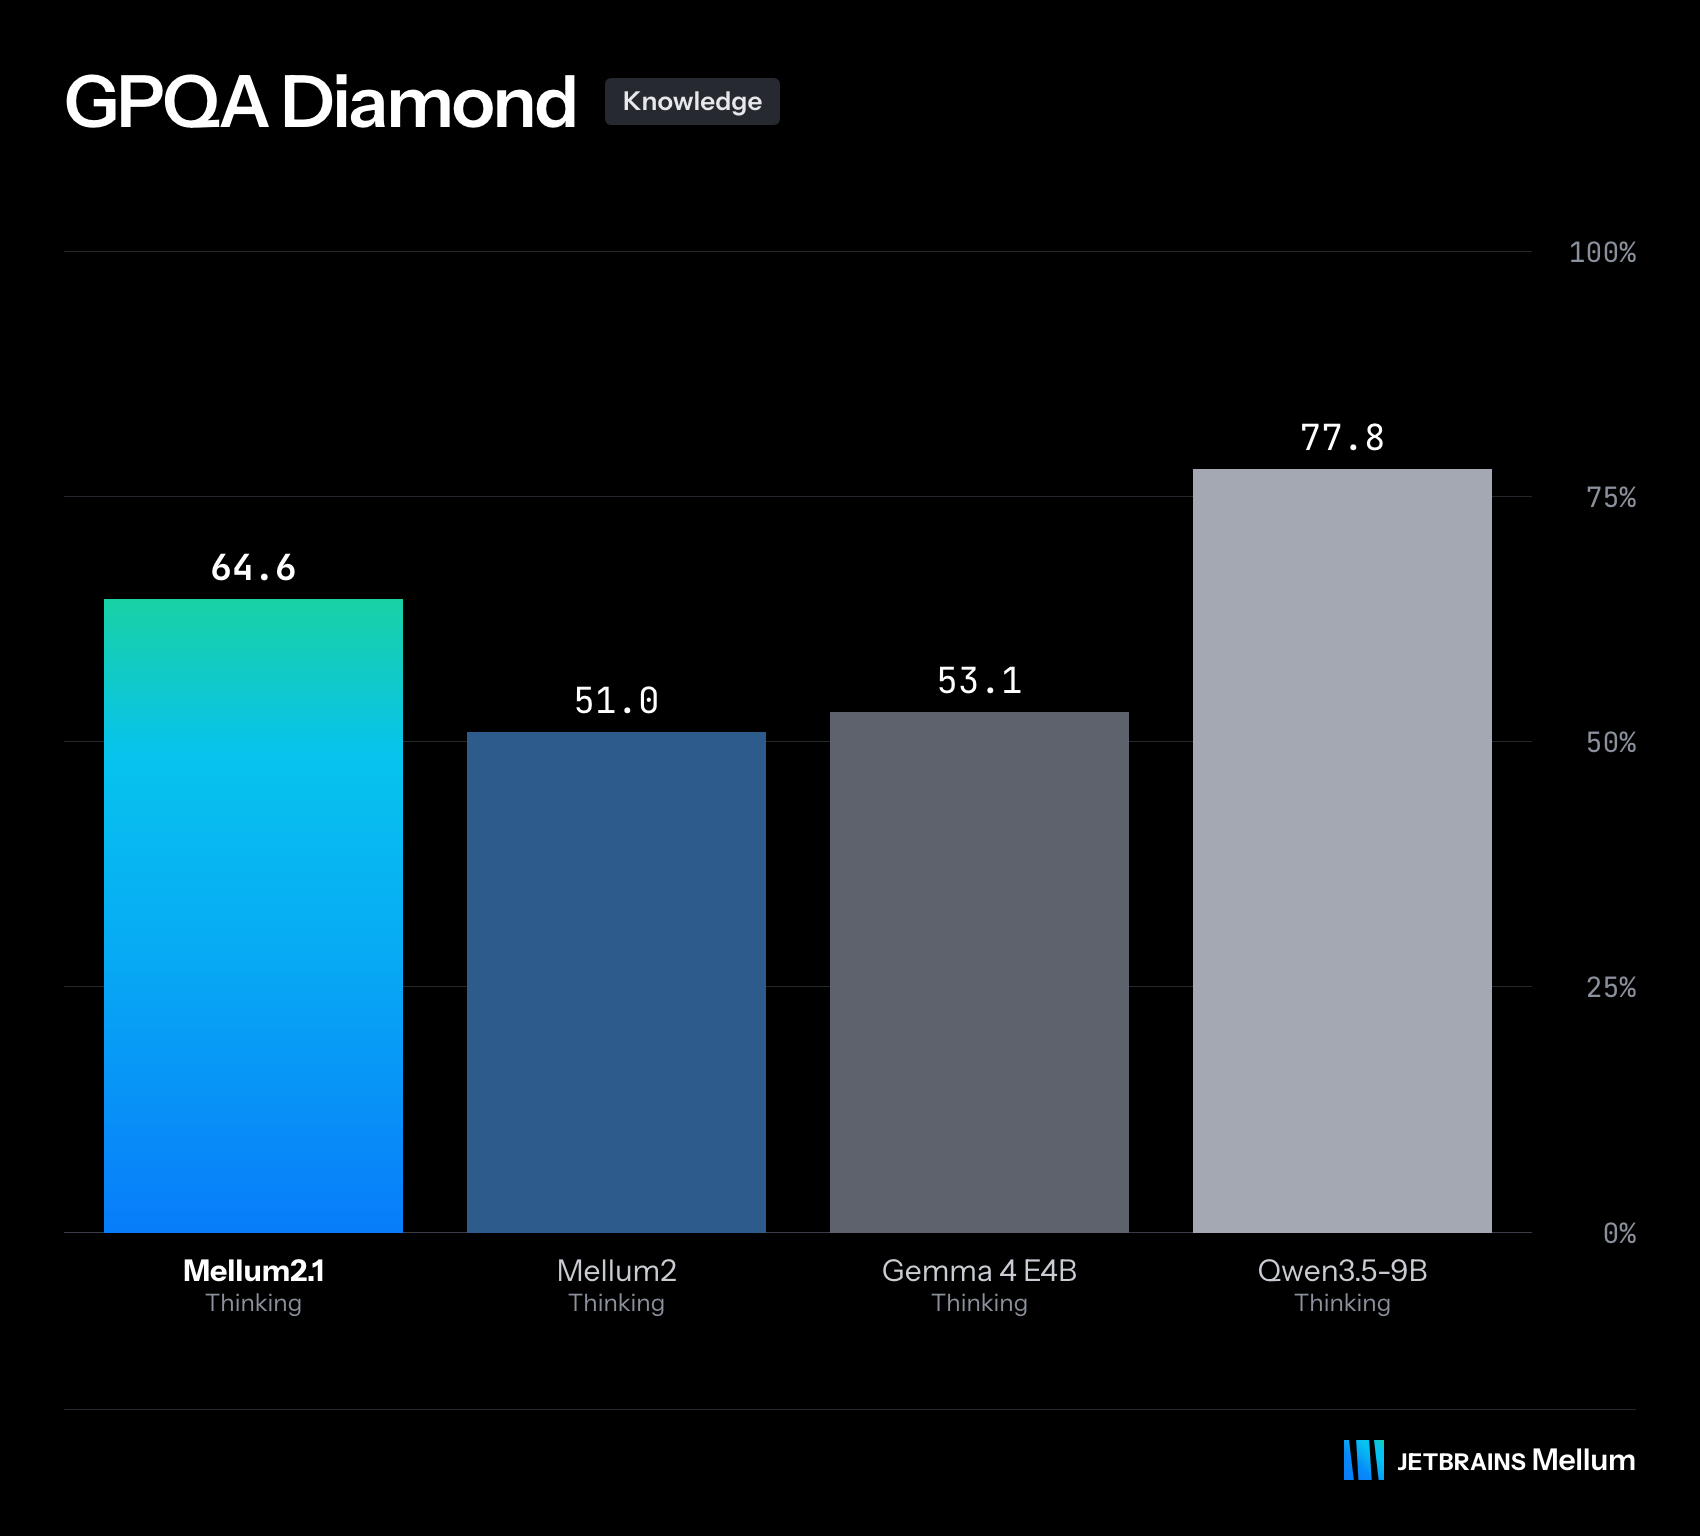
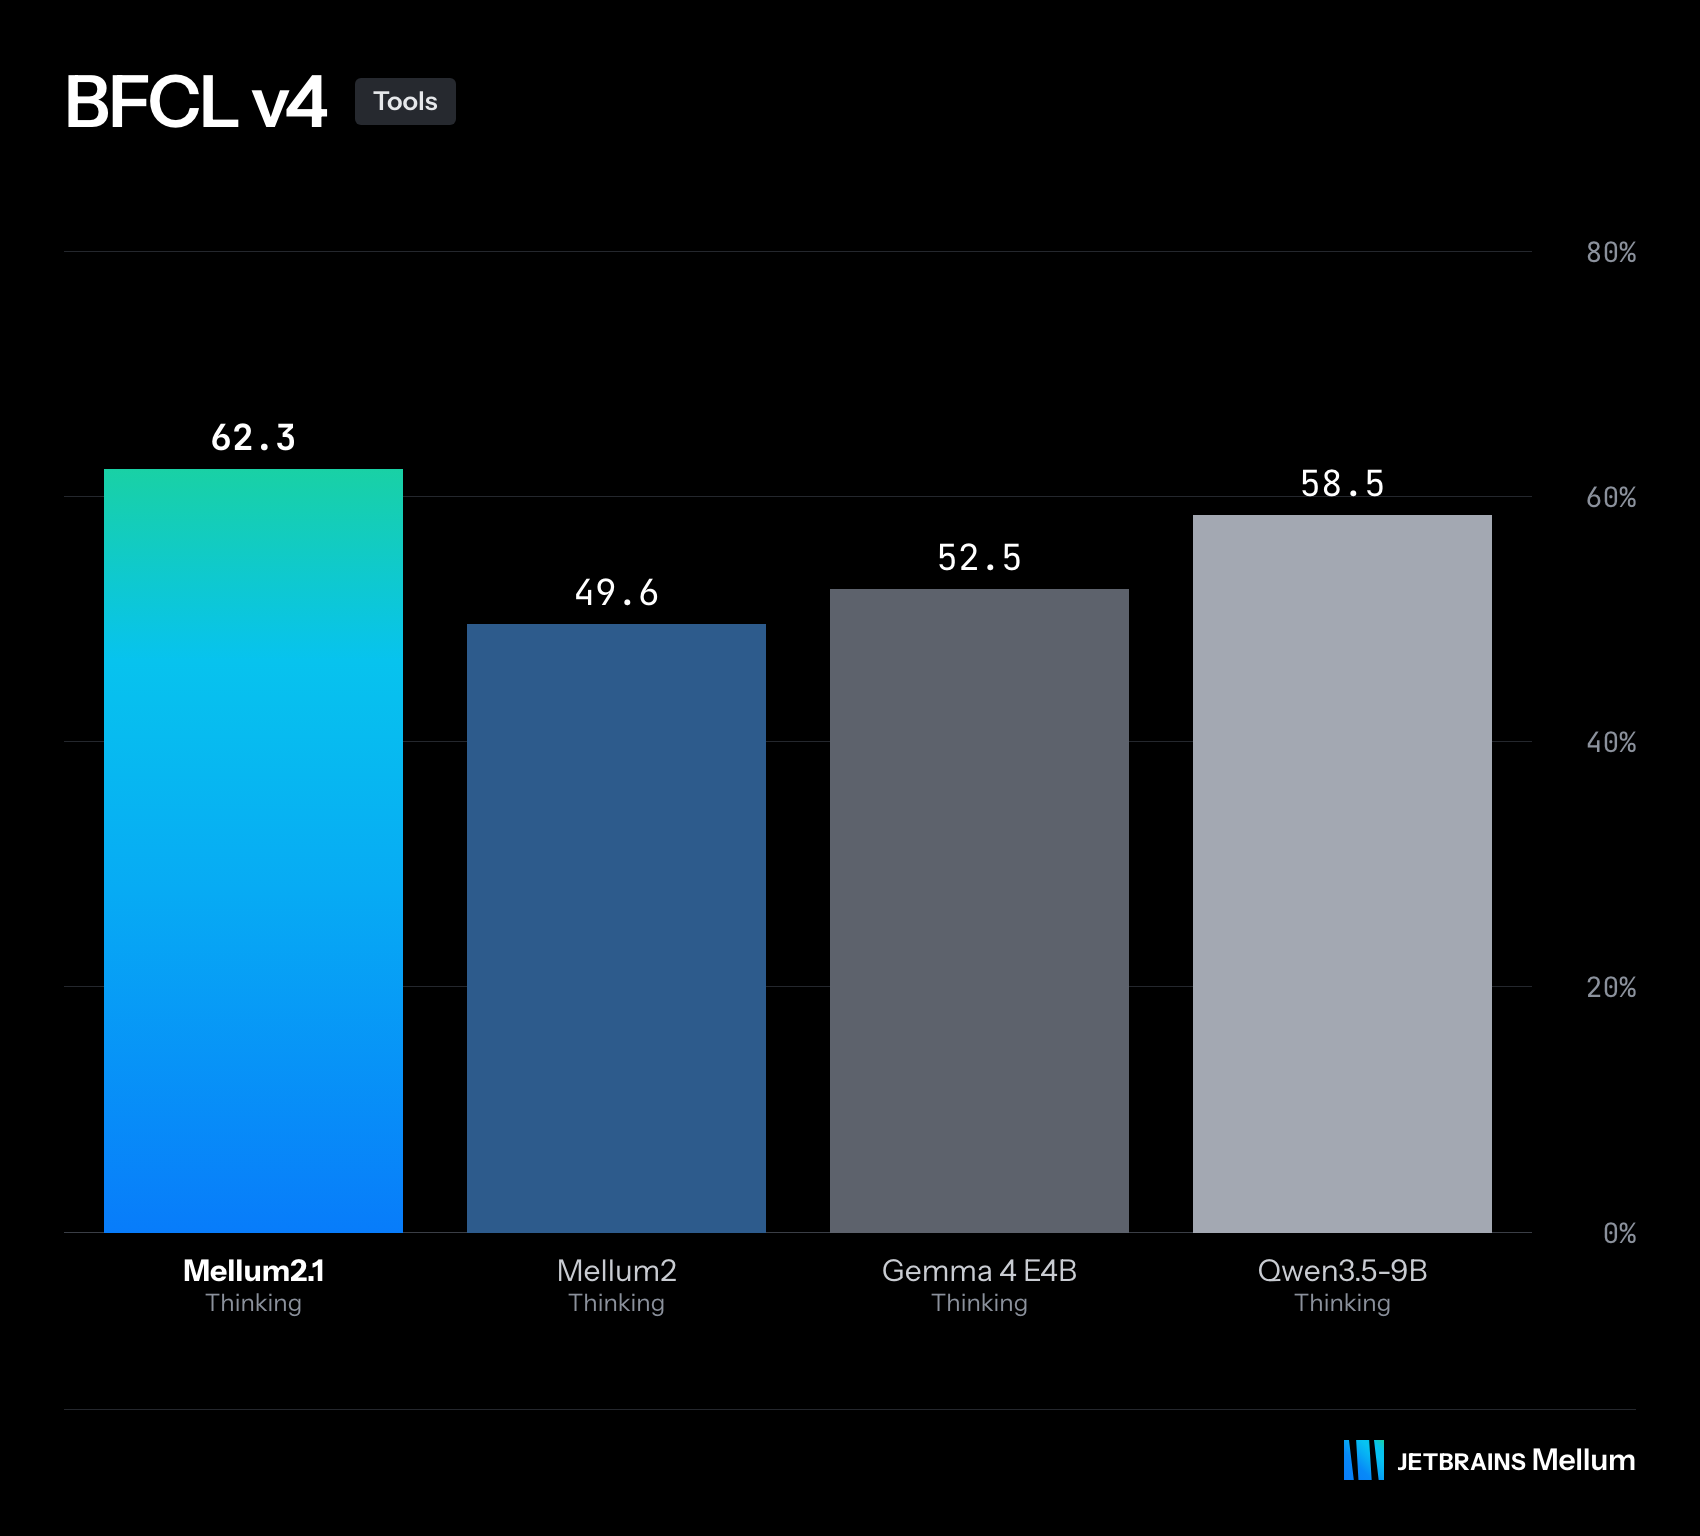
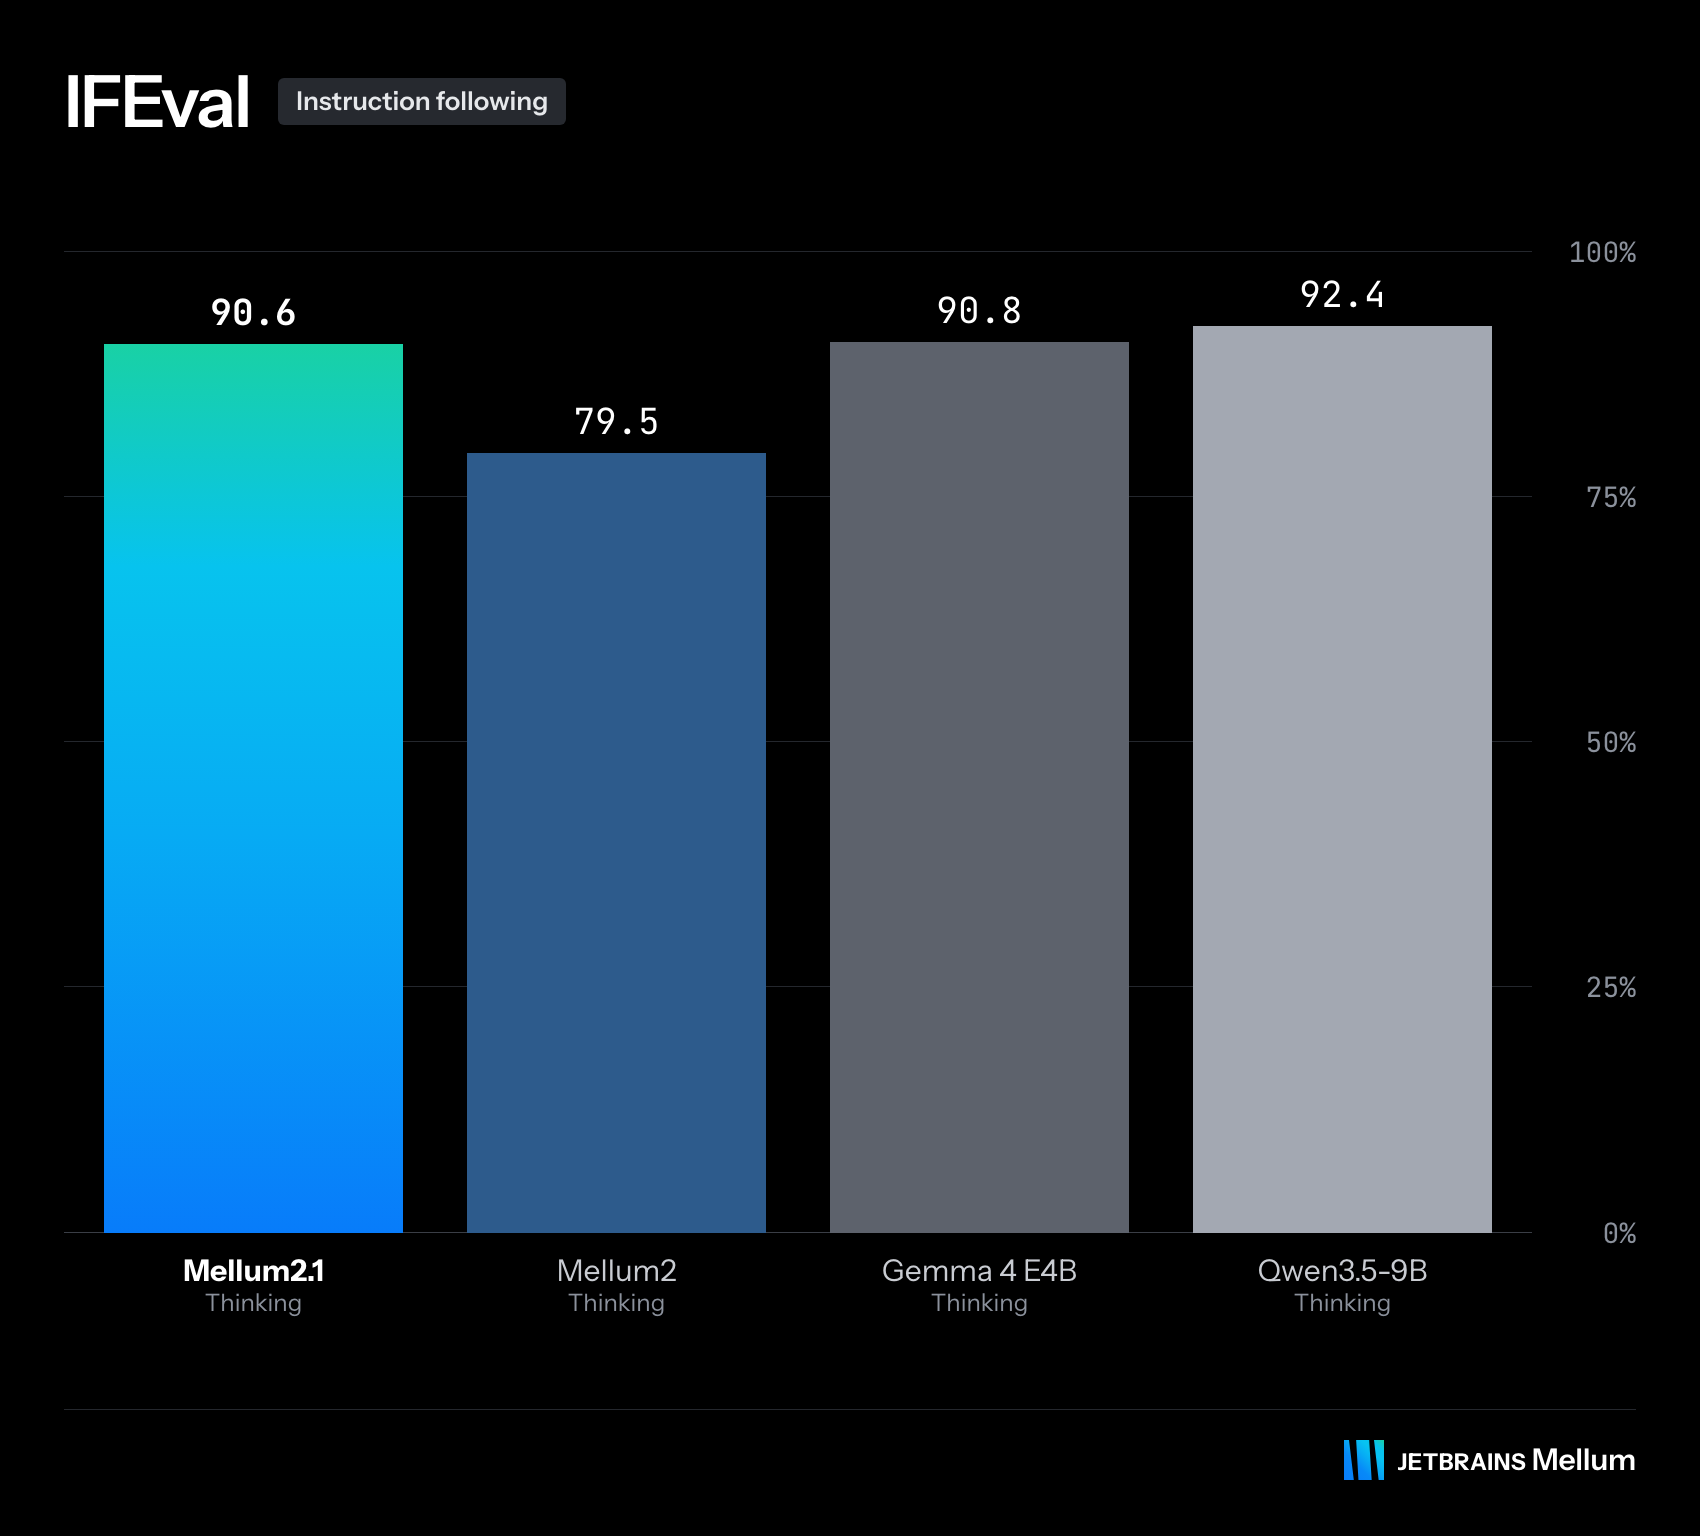
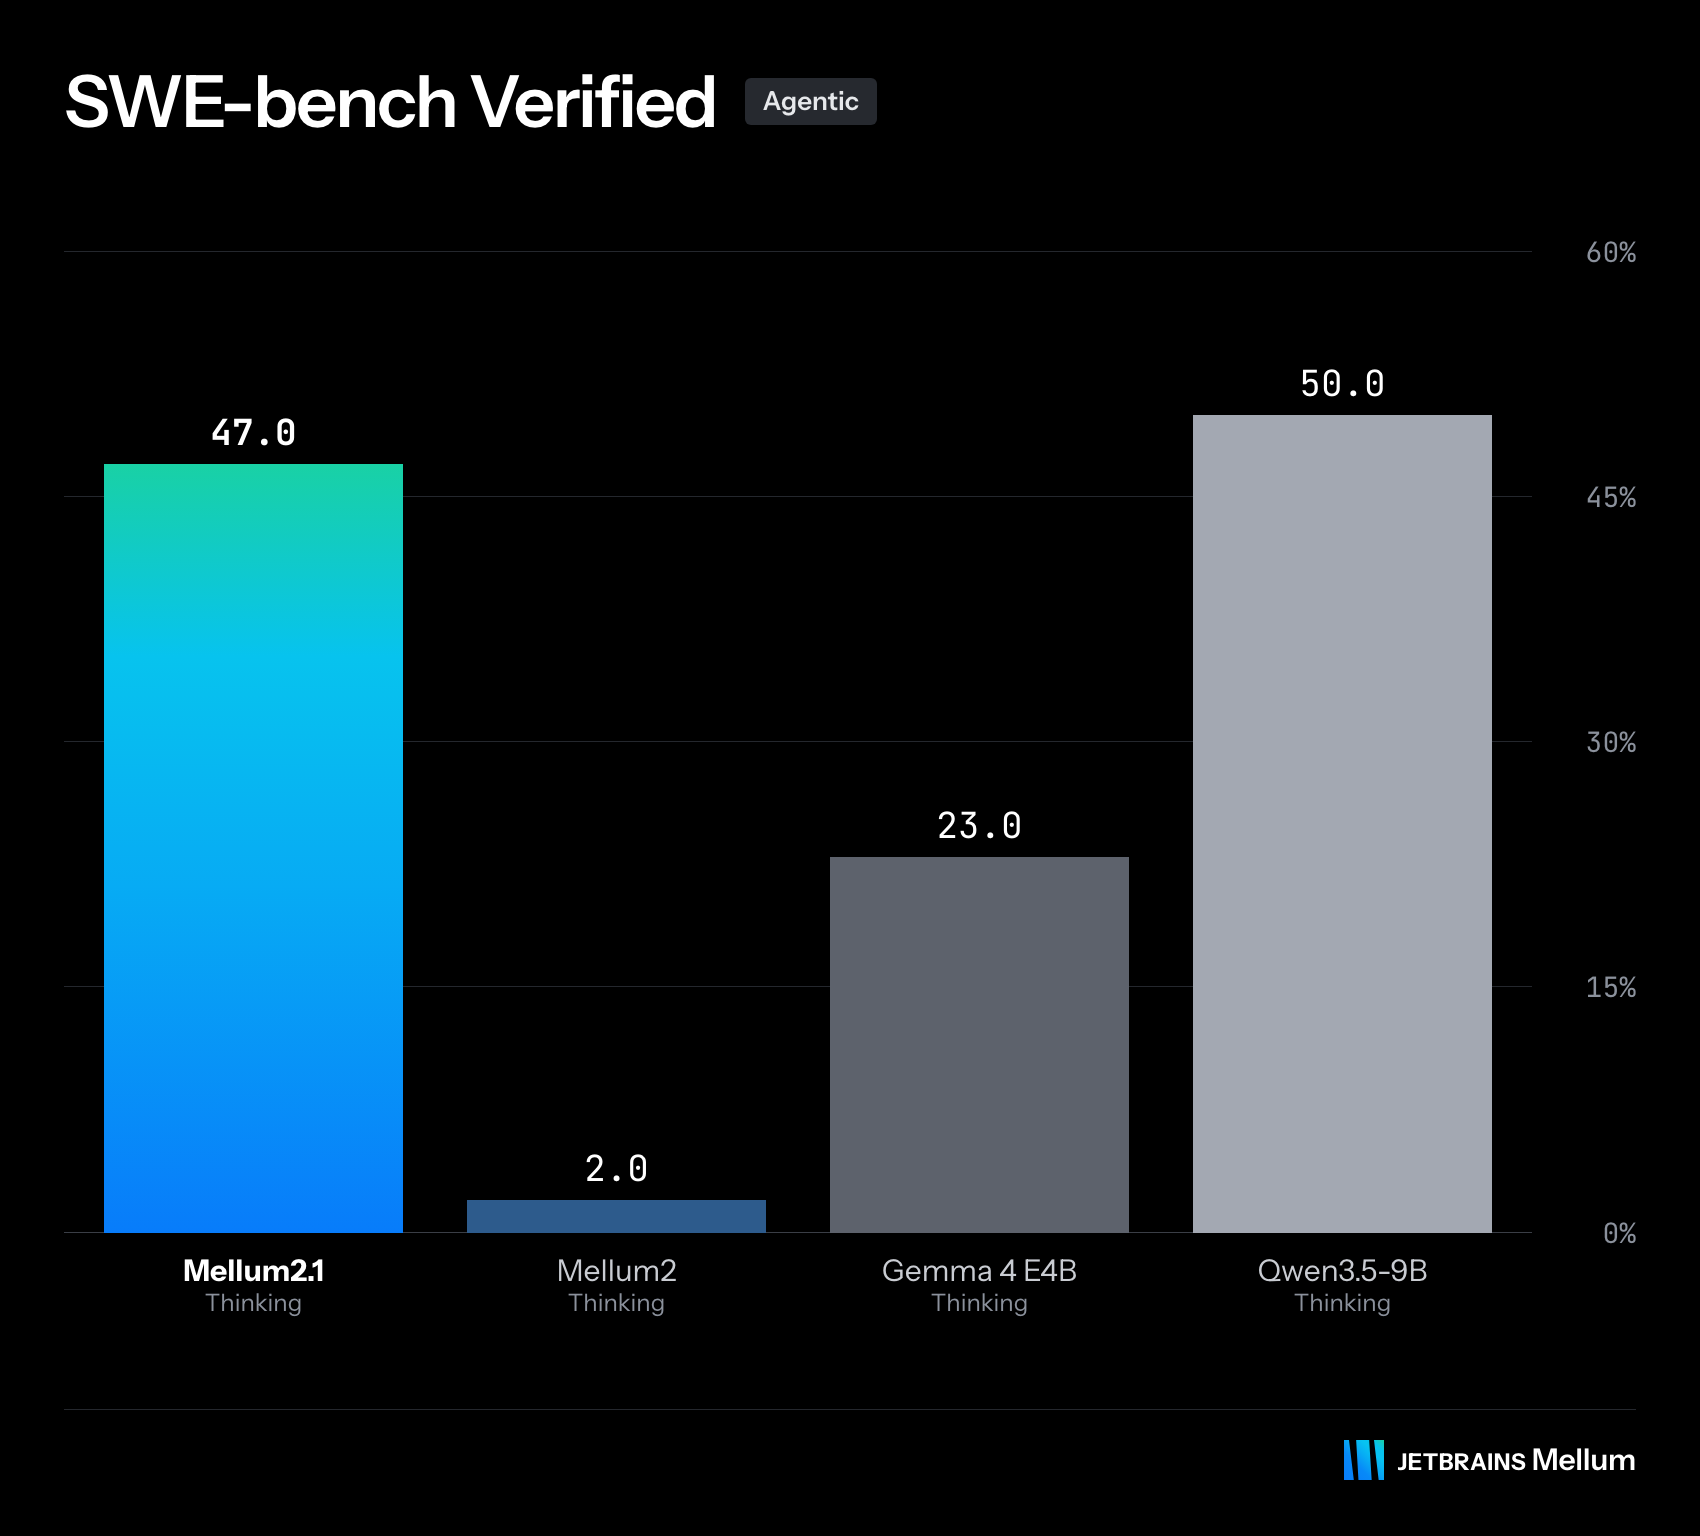
We compared Mellum2.1 with Mellum2 – as well as two open models of a similar class, Qwen3.5-9B and Gemma 4 E4B – using the same evaluation setup for all of them.

The biggest improvement is in agentic coding, where Mellum2.1 advanced the most compared with Mellum2. The model also got better across the board, showing gains in coding, competitive programming, math, tool calling, and general knowledge, and it holds up on hard problems as well as everyday ones.
Speed
Post-training didn’t touch the architecture, so Mellum2.1 is as fast as Mellum2, and multi-token prediction (MTP) makes it faster.
Under heavy load, Mellum2.1 is the fastest model in the group and serves almost twice as many tokens as Qwen3.5-9B. For a single request, MTP makes it about 1.6 times faster.

Key use cases for Mellum2.1
- A capable worker inside agentic systems: Mellum2.1 can handle different parts of an agent’s plan, from identifying the root cause of a failing test to drafting and checking a fix.
- Problems beyond coding: Mellum2.1 is a capable general assistant, too. It handles everyday questions and works through hard math and reasoning problems step by step.
- Private, self-hosted deployment: Run Mellum2.1 locally or on your own infrastructure to keep code and data fully under your control.
Get started with Mellum2.1
Mellum2.1 is available on Hugging Face. GGUF builds for llama.cpp, Ollama, and LM Studio, as well as the multi-token prediction (MTP) head for speculative decoding in vLLM, are coming soon.
If you’re building coding agents, sub-agents, or AI tools that run on your own infrastructure, we’d love for you to try Mellum2.1. Tell us what works and what doesn’t. Your feedback will shape the next version.
Open source is how better models get made.